
Unicode Han Character '(same as 無) without, none, a negative (a variant 嬭) to burn food in cooking; singed; burnt' (U+2DD0A) |
  |
(same as 無) without, none, a negative (a variant 嬭) to burn food in cooking; singed; burnt
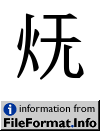
(same as 無) without, none, a negative (a variant 嬭) to burn food in cooking; singed; burnt
| Name | (same as 無) without, none, a negative (a variant 嬭) to burn food in cooking; singed; burnt |
| Block | CJK Unified Ideographs Extension F |
| Category | Letter, Other [Lo] |
| Script | Han (Hani) |
| Combine | 0 |
| BIDI | Left-to-Right [L] |
| Version | Unicode 10.0 (June 2017) |
| Unicode Han Data | |
|---|---|
| kIRG_GSource | GFC-020 |
| kPhonetic | 911* 914* |
| kCantonese | mou4 |
| kTraditionalVariant | U+3DFB |
| kRSUnicode | 86.4 |
| kMandarin | mó |
| kTotalStrokes | 8 |
| kDefinition | (same as 無) without, none, a negative (a variant 嬭) to burn food in cooking; singed; burnt |
| HTML Entity (decimal) | 𭴊 |
| HTML Entity (hex) | 𭴊 |
| How to type in Microsoft Windows | Alt +2DD0A |
| UTF-8 (hex) | 0xF0 0xAD 0xB4 0x8A (f0adb48a) |
| UTF-8 (binary) | 11110000:10101101:10110100:10001010 |
| UTF-16 (hex) | 0xD877 0xDD0A (d877dd0a) |
| UTF-16 (decimal) | 55,415 56,586 |
| UTF-32 (hex) | 0x0002DD0A (2DD0A) |
| UTF-32 (decimal) | 187,658 |
| C/C++/Java source code | "\uD877\uDD0A" |
| Python source code | u"\U0002DD0A" |
| More... | |
| Java Data | |
|---|---|
| string.toUpperCase() | 𭴊 |
| string.toLowerCase() | 𭴊 |
| Character.UnicodeBlock | CJK_UNIFIED_IDEOGRAPHS_EXTENSION_F |
| Character.charCount() | 2 |
| Character.getDirectionality() | DIRECTIONALITY_LEFT_TO_RIGHT [0] |
| Character.getNumericValue() | -1 |
| Character.getType() | 5 |
| Character.isDefined() | Yes |
| Character.isDigit() | No |
| Character.isIdentifierIgnorable() | No |
| Character.isISOControl() | No |
| Character.isJavaIdentifierPart() | Yes |
| Character.isJavaIdentifierStart() | Yes |
| Character.isLetter() | Yes |
| Character.isLetterOrDigit() | Yes |
| Character.isLowerCase() | No |
| Character.isMirrored() | No |
| Character.isSpaceChar() | No |
| Character.isSupplementaryCodePoint() | Yes |
| Character.isTitleCase() | No |
| Character.isUnicodeIdentifierPart() | Yes |
| Character.isUnicodeIdentifierStart() | Yes |
| Character.isUpperCase() | No |
| Character.isValidCodePoint() | Yes |
| Character.isWhitespace() | No |
